
Why AI Motion-Transfer Renders Fail (1,526 Renders Analyzed)
We looked at 1,526 renders. Clip length predicted failure far better than resolution or image quality — and almost every failure was server-side, not a bad photo.
 Animaker Dev
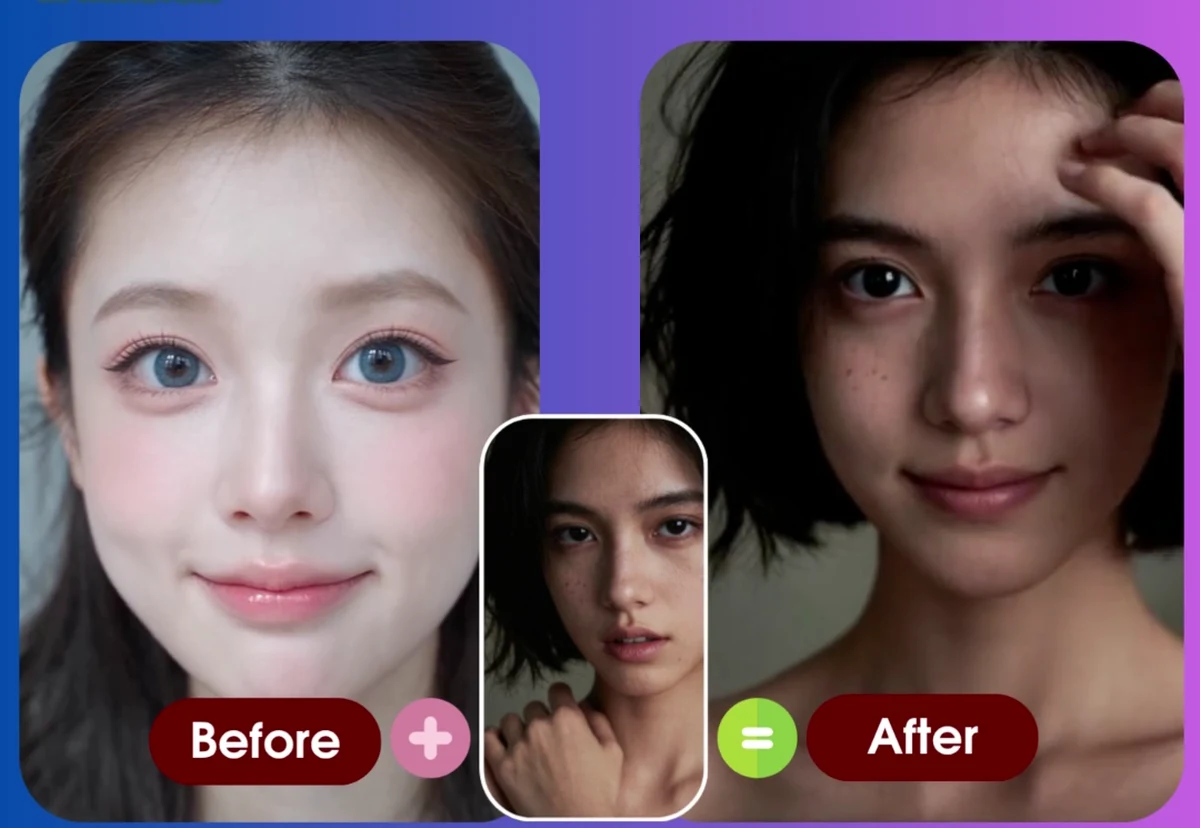
If your AI video came back broken, the instinct is to blame the photo. We looked at 1,526 renders produced on Animaker between launch and October 2026, and the data says that instinct is usually wrong.
Almost every failure in that set was server-side: the generation job died, a queue limit was hit, or a worker timed out before it started. Not one of the top four failure reasons was a bad image.
That matters because it changes what you should do. You cannot fix a queue with a better selfie. But there is one input you control that moved the failure rate by more than three times.
The one thing that actually predicts failure
Clips were bucketed by length, and the failure rate per bucket was recorded:
| Reference clip length | Renders | Failed | Failure rate |
|---|---|---|---|
| 0–5 s | 27 | 4 | 14.8% |
| 5–10 s | 300 | 69 | 23.0% |
| 10–15 s | 983 | 219 | 22.3% |
| 15–30 s | 171 | 69 | 40.4% |
| over 30 s | 45 | 22 | 48.9% |
A clip under 15 seconds fails roughly one time in five. A clip over 30 seconds fails about one time in two.
The mechanism is memory, not luck. Every extra second of reference is more frames the model has to hold at once — more per-frame latent state, resident for longer. When that exceeds the GPU memory available on the inference host, the job does not degrade gracefully; it dies. The same thing happens when the host's compute is saturated and the scheduler cannot place the job at all. Longer clips make both more likely, which is why the failure curve bends upward exactly where it does.
So the single most effective thing you can do before uploading is cut the reference down to the movement you actually want. Three to ten seconds is the sweet spot. You are not losing anything: the output is as long as the reference, and a tight ten-second clip of the movement you care about beats a rambling minute.
What did not matter
Resolution. 720p renders failed at 25.0%; 512p renders failed at 26.7%. That difference is noise. Choosing a lower resolution does not buy you reliability, and paying for a higher one does not cost you any.
Generation mode. Motion transfer failed at 25.9%; character replacement at 19.6%. Character replacement is somewhat more forgiving, but the gap is not large enough to plan around.
This is useful mostly as a negative result: if a render failed, it was almost certainly not because the file was too big, the resolution too high, or the mode wrong.
Where the failures actually came from
Grouping the 383 failed renders by error reason:
| Reason | Share of failures |
|---|---|
| Out of GPU memory, compute exhaustion, or a safety-review block | 43% |
| Provider account out of balance | 30% |
| Provider concurrency / queue limit reached | 12% |
| Timed out waiting for available capacity | 9% |
| Everything else (network, 5xx, misc.) | 6% |
Every row in that table is infrastructure. None of them is "the photo was bad" or "the clip was wrong".
In hardware and policy terms, the 43% "workflow failed" bucket is a mix of two things that look identical from the outside: the job ran out of GPU memory or compute on the inference host, or an automated safety review declined it and the workflow aborted. Neither degrades gracefully — both simply stop. The 12% queue-limit row is the same capacity shortage surfacing earlier, at submission, when concurrency on the provider's side is already saturated. The balance and timeout rows are the same story one step further out.
In the last seven days, after the balance and queue handling were fixed, 236 renders ran with an 87% completion rate.
We are publishing this because the alternative is what most tools do: let a render fail silently and leave you guessing which of your two files was at fault. If a job fails here, the credit comes back automatically, and the reason is recorded.
Five rules that decide your render
- Keep the reference clip between 3 and 10 seconds. Under 15 seconds if you must go longer. This is the biggest single lever.
- One person in frame. Two people means the model has to choose whose body to drive, and it chooses badly.
- Keep the camera still. Cuts, zooms and pans make the background move while the performer does not, which reads as ambiguous motion.
- Front-facing, upper body visible, nothing across the face. A face a few dozen pixels wide has too little identity signal to carry over.
- Empty hands. The model cannot reliably separate a hand from the object it is holding.
None of these is about the tool being fragile. They are about giving the model an unambiguous answer to two questions: who is this, and what are they doing.
Try it with one good clip
The first video is free and needs no card. If you want to check the single thing that matters most, take the dance clip you were going to use, trim it to eight seconds, and upload that.
Start with a photo and a short clip →
If it fails, you get the credit back and a recorded reason. If it works, you have a file you can download and post — no watermark, no subscription.
Method and limits
Renders counted from launch through 20 October 2026, all markets, all plans. Failure rate is failed renders divided by finished renders (success plus failure); jobs still running are excluded. Length buckets use the submitted reference duration. Resolution and mode figures come from the same set. Percentages are rounded, so rows may not sum to exactly 100%.
The limits are worth stating: this is one product's data, not an industry benchmark, and it measures what came out of the pipeline rather than the perceived quality of a successful render. A render that completed is counted as a success even if the result looked wrong to its author.
Continue reading
7 Reference Action Video Tips for Better AI Motion Transfer
Learn how to shoot or choose better reference action videos for AI motion transfer, avoid failed generations, and improve photo-to-video results.
Animaker DevWhy AI Video Generation Fails — And How to Get Better Results
Most AI video failures start with the two inputs, not the model. See why photo-to-video tasks fail, why results look distorted, and which uploads fix both.
Animaker Dev
Motion Transfer vs Character Replacement vs Template Libraries: Three Ways to Animate a Photo
A plain-language comparison of the three approaches to animating a photo with AI — what each one keeps, what it needs from you, and how to choose between them.
Animaker Dev Team